Reinforcement learning in simulated environments
Sensori Robotics
I implemented Python training logic for a capstone robot learning to follow edges for outdoor maintenance. My work included simulated environments, custom rewards, scripted evaluation, performance visualizations, and documentation for continued development.
Why simulation
Our capstone task was to teach a legged ground robot to follow an edge for outdoor maintenance. Simulation let us develop and evaluate navigation behavior before physical deployment.
On the Fall 2025 capstone team at UT Dallas, I was a developer focused on implementation and documentation. I worked on the simulation environments, reinforcement-learning training setup, and validation workflows.
Building the environment
I recreated real-world environments in NVIDIA IsaacSim and helped define the IsaacLab training setup, including what the robot observes and which actions it can take.
I implemented the task logic in Python:
- Custom rewards and penalties supplied feedback for learning edge-following behavior.
- Termination conditions defined when a training episode ends.
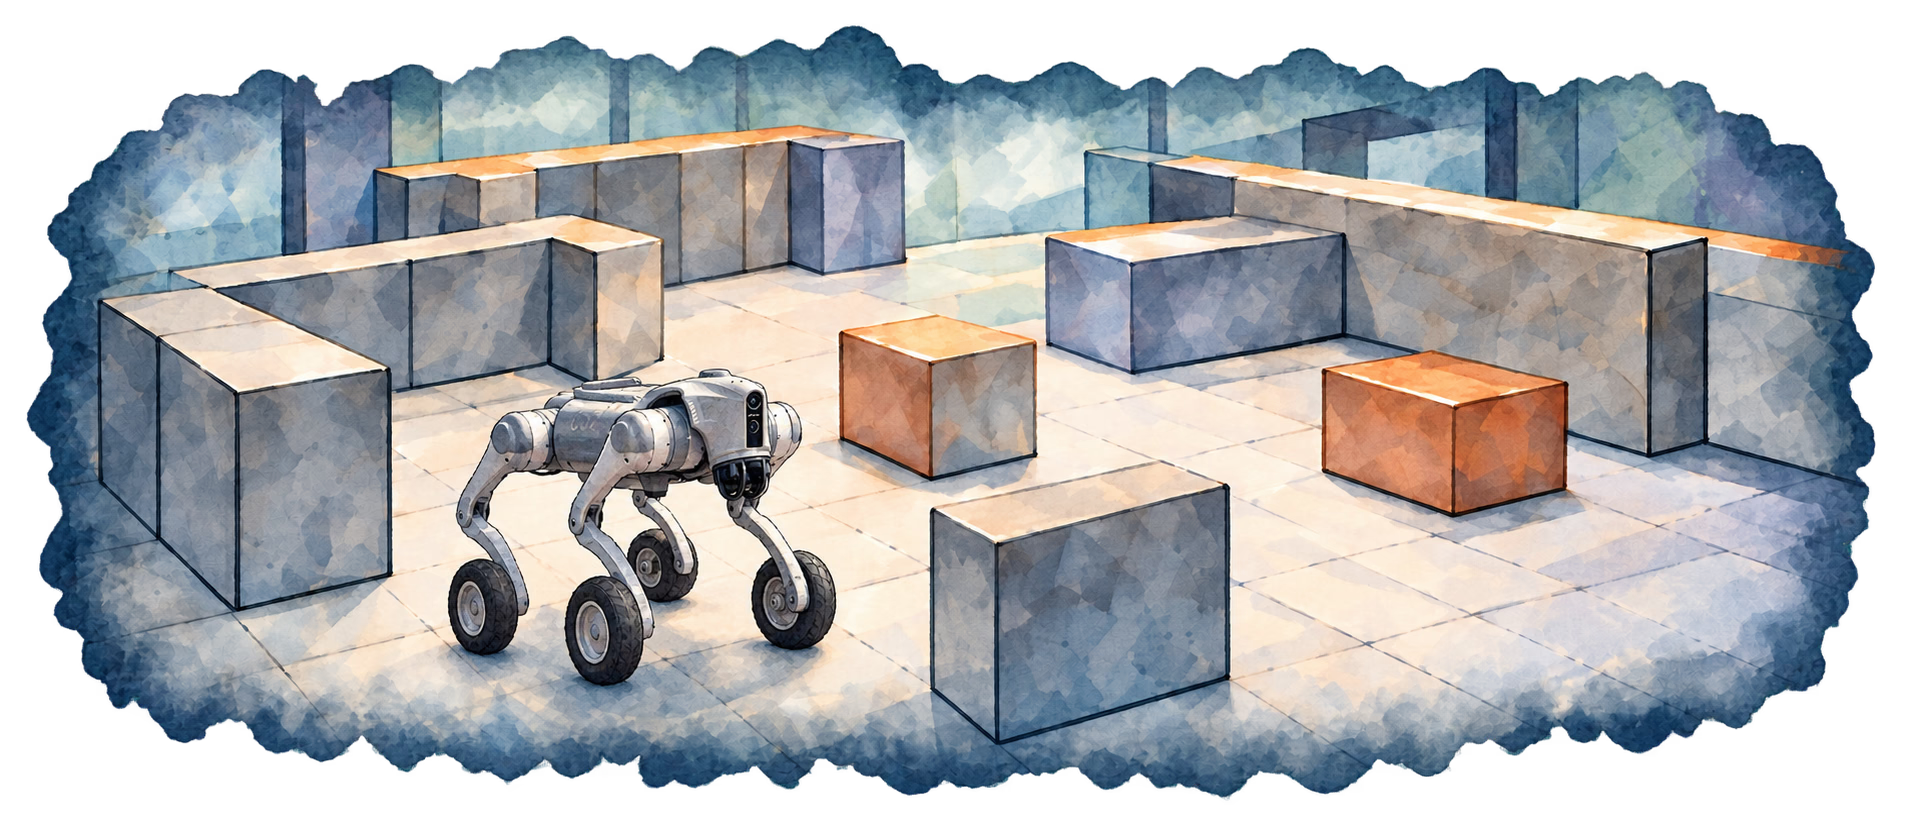
Concept illustration, not a simulator screenshot or measured result.
Training loop
The team used Proximal Policy Optimization (PPO), a reinforcement-learning algorithm for continuous control. IsaacSim provided the physics environment; IsaacLab organized the training loop. My implementation work focused on the environments and task logic around the algorithm.
I designed and trained control policies through iterative experimentation. I analyzed simulation performance data and created visualizations to evaluate behavior across varying terrain conditions and edge-following scenarios.
I also implemented scenario checks and scripted test runs, giving the team repeatable ways to evaluate behavior in simulation.
- Observe
- Choose
action - Simulated
response - Reward/end
condition - Continue
or reset
Hardware boundary
I documented the architecture connecting perception inputs, navigation logic, and motor control. The documentation included technical references and onboarding materials for continued development.
That connection also defined a boundary: the model’s continuous outputs need to become commands the physical robot can execute. Our simulation work supported development and evaluation; physical deployment still required validation on the robot.
What the work produced
My deliverables brought together executable training-task logic, simulated environments, evaluation scripts, performance visualizations, and architecture documentation. They supported the team’s navigation experiments and provided references for continued development.
Source code and detailed results are covered under NDA and are not publicly available.